Featured projectactive2026
Tiles: Scheduling LLM Decoding as a Graph of Tiles
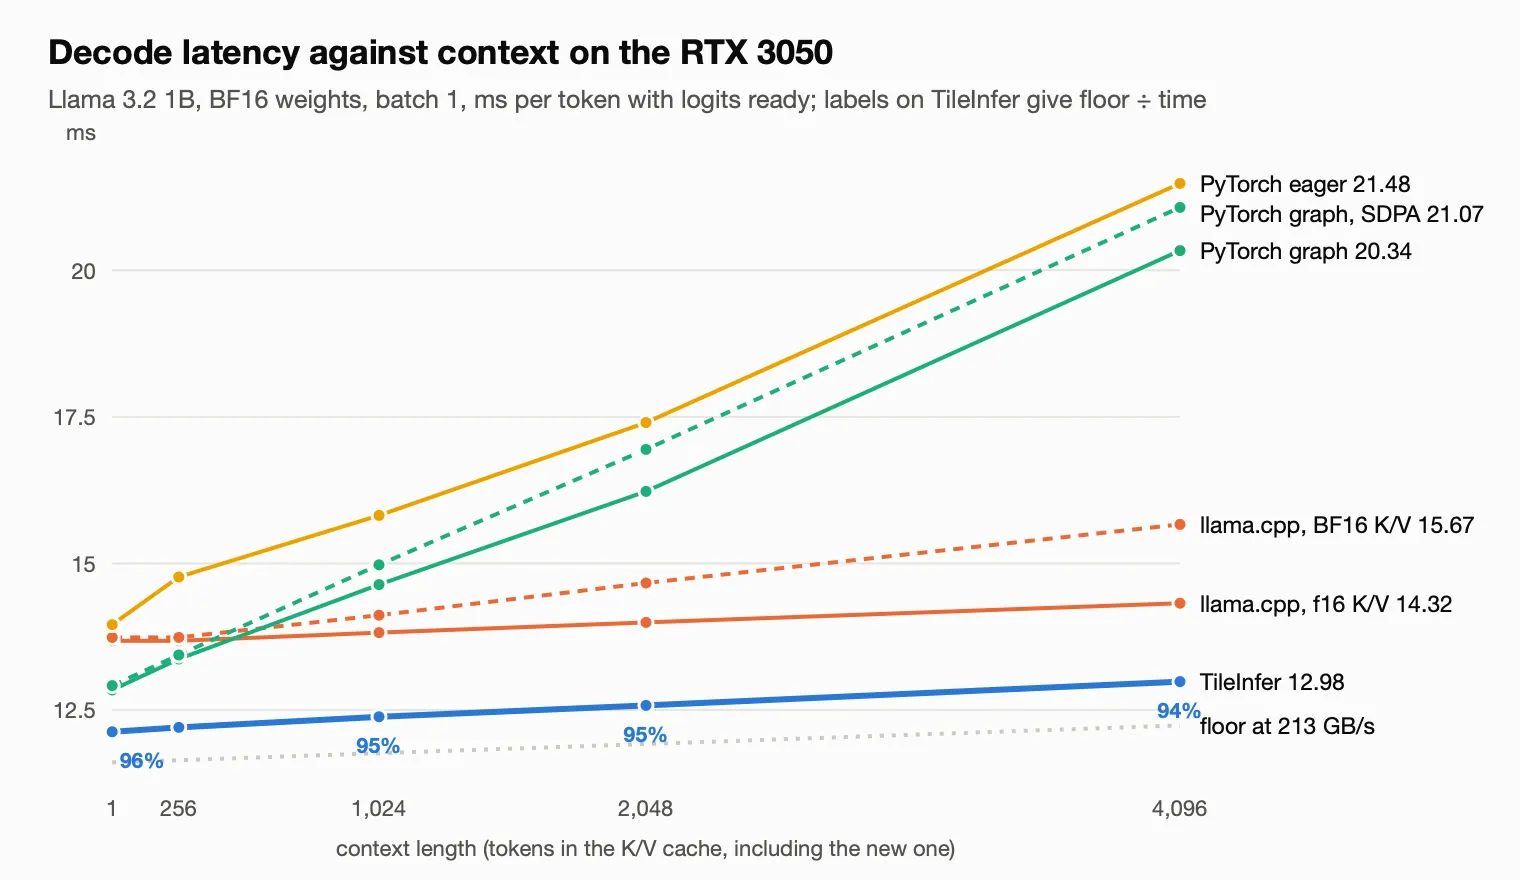
A research runtime that turns LLM decoding from a graph of kernels into a graph of tiles. Tiles are the atomic unit of scheduled work: an offline planner assigns every tile to a fixed worker, and one persistent CUDA kernel executes that schedule for every token of Llama 3.2 1B on an 8 GB RTX 3050.
CUDAGPU programmingmegakernels
View project