Adaptive Software Rasterization with CUDA
A CUDA software rasterizer that runs the graphics pipeline entirely on the GPU. The framework manages rasterization and adaptive sampling in software, generating additional work when needed while achieving interactive frame rates.
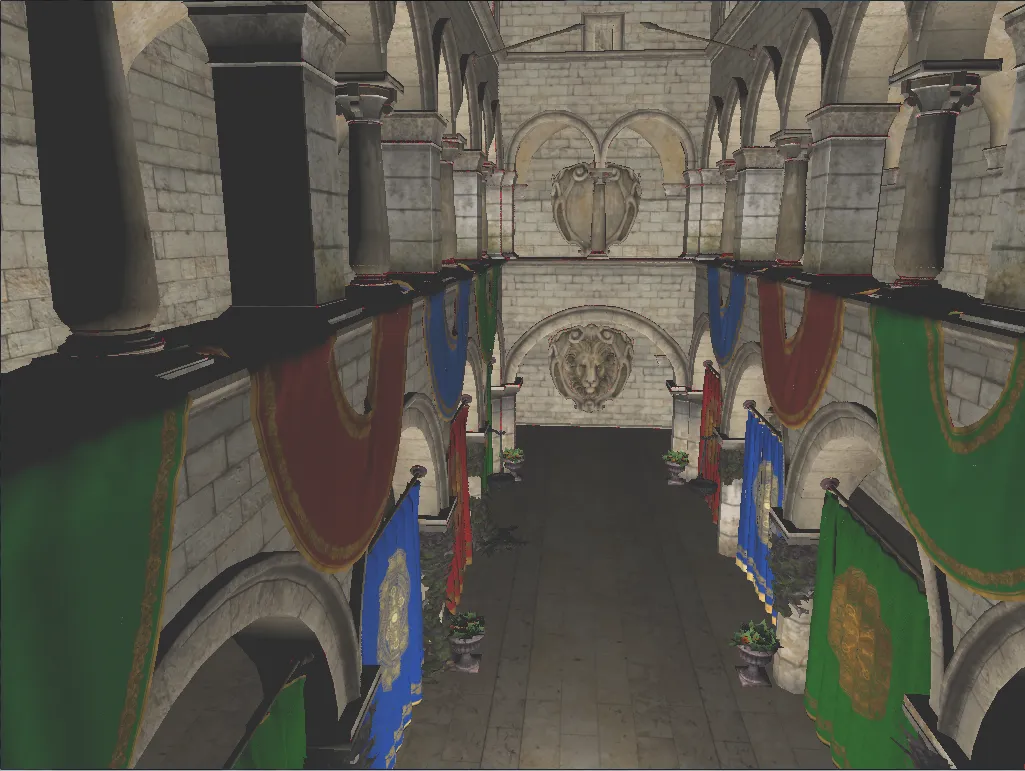
I was surprised to find that I had never published the code for my master’s thesis, so I uploaded it to GitHub.
The repository contains a software rasterization framework that runs entirely on the GPU using CUDA and implements a form of adaptive rasterization.
Adaptive Rasterization for Microdisplaced Surfaces
In my thesis I proposed a rasterization-based pipeline for real-time rendering. It efficiently renders highly detailed objects by applying microdisplacement to surfaces: the pipeline performs displacement mapping and evaluates Bézier triangles on a per‑pixel basis. I implemented the rendering pipeline in software and achieved interactive frame rates by executing it completely on the GPU.
To apply accurate microdisplacement, the surface is modified by changing the positions of individual shading fragments. This is problematic for contemporary graphics pipelines because some pixels can end up without fragments. My modified pipeline realizes adaptive rasterization: additional fragments can be sampled adaptively after the usual rasterization stage. Adaptive sampling of new fragments guarantees that all pixels are shaded, so surfaces can be displaced without costly tessellation, which is inefficient for small, detailed displacements.
Suffice to say, the idea never really took off. Partly because I never finished the corresponding research paper. And even though it’s an interesting idea, it would likely require a costly hardware redesign.
Scheduling Work on the GPU
Running the pipeline in CUDA also meant scheduling its stages in software. I used a persistent megakernel based on Whippletree: GPU workers take tasks from stage-specific queues, and stages can add new tasks while the kernel is running. When adaptive sampling needs another fragment, it adds one to its queue; that fragment passes through displacement before returning to adaptive sampling. This handles work generated during rendering without a new kernel launch for each pass, but requires explicit queue management and synchronization. I explain the approach and its connection to modern AI inference in Persistent Threads and Megakernels.